Every headline number on this site is also listed, one sourced sentence each, in the fact index, which downloads as CSV or JSON.
Blood types
The blood-type explorer keeps three sources separate: Stanford Blood Center's U.S. reference, Lifeblood's Australian estimates, and NHS Blood Donation's donor table. Stanford credits the AABB Technical Manual, 18th edition, without stating the observation year or sample size. Lifeblood identifies 2019 patient pathology results. The NHS table is dated February 2026 and describes donors rather than the UK general population.
Only the eight factual percentages from each reference are transcribed. Charts and explanatory copy are original; source logos, diagrams and photographs are not reused. The downloadable CSV identifies the source, population, period and limitations on each row. Source-page hashes and the reviewed transcription are retained with the generator. Website retrieval in September 2026 is not the data's observation year.
For a percentage p, 100 divided by p gives an approximate 1-in-N frequency. The displayed denominator is rounded while the percentage retains its source precision. Rank is one plus the number of types with a higher percentage; equal values tie. A comparison uses two percentages from the same source. It is a descriptive ratio, not a statistical significance test. The Australian rounded percentages sum to 102%; they are neither normalized nor placed in a 100% stacked chart. Each result's 100-square graphic depicts only its own percentage, including fractional squares.
The red-cell compatibility matrix follows Lifeblood's recipient-to-donor table for ABO/RhD groups. It does not describe plasma, platelet or whole-blood compatibility. Other antigens and antibodies matter, so clinical testing and matching remain necessary. Frequency among eight groups is not a diagnosis of a clinically rare blood phenotype.
Eye color
The eye-color chart leads with eye colors recorded on 235,423,085 active U.S. driver’s licenses in 31 states (2016 data), published by Hashem, Menicacci and Granet in PLOS ONE in September 2025 under CC BY 4.0: brown or black 53%, blue 23.7%, hazel 10.3%, green 9%, gray 0.7%, and 3.3% pink, maroon, dichromatic or unknown. Colors are as recorded on the license. Amber, which licenses do not list, comes from YouGov’s May 2023 poll of 1,000 U.S. adult citizens (weighted; stated margin ±3.7 points): brown 40%, blue 23%, hazel 15%, green 11%, gray 4%, amber 4%, other 0% and not sure 1%. The American Academy of Ophthalmology’s account of a 2014 Harris Poll remains a third reference.
Each color uses the first of these that measures it, in that order, and shows the others beside it; the shares are never averaged or pooled, and combined groups are never ranked. Complete heterochromia comes from Dabkowski and colleagues’ study of 11,111 portraits of U.S. Military Academy cadets: 7 cases, 0.063%, 95% interval 0.028–0.133%. Partial heterochromia was not counted.
Source-labelled SVG charts, CSV tables and local cards preserve these limits. The color swatches are original illustrations rather than a diagnostic scale. The genetics explanation follows MedlinePlus Genetics: multiple genes influence pigmentation, so a single dominant/recessive chart cannot yield reliable baby-eye probabilities from parental color labels. This product does not take photos or infer ancestry.
Adult height
The adult height percentile calculator uses the CDC / National Center for Health Statistics report Anthropometric Reference Data for Children and Adults: United States, August 2021–August 2023, Table 7, published June 2025. The report is in the public domain. Our downloadable 16-group CSV preserves the centimeter values, sample sizes, means and standard errors of the means from that table.
NHANES represents the U.S. civilian noninstitutionalized population. Its adult table covers age 20 and over, split into male and female categories and seven age bands. Examination sample sizes are unweighted; the published percentiles use survey weights. The all-adult row already includes the individual age bands, so those sample counts must not be added to it.
Between adjacent published heights, we interpolate the percentile linearly and round it to a whole number for display. The source itself rounds heights to 0.1 cm. The result is an approximation, not an exact rank of every person or a worldwide comparison. We do not fit a normal distribution or substitute the standard error of the mean for a standard deviation.
Outside the published range, the result retains a bound. Both age-80+ groups omit the 95th percentile because its standard error could not be computed; their upper published point is the 90th. The omission remains blank in CSV and a dash in the reference table. We never extrapolate a “1 in a million” figure or treat missing values as zero. Inputs and personalized cards stay local, and height results are not multiplied by name, birthday or language frequencies.
Handedness
The left-handedness page reports the random-effects estimates of Papadatou-Pastou and colleagues’ 2020 meta-analysis in Psychological Bulletin: 200 studies, 262 datasets and 2,396,170 people, analyzed in five separate groups by how each study classified hands (left or right only; left, mixed or right; right or not right; every study together; and mixed-handed). Each figure keeps its 95% confidence interval. The splits by sex, ancestry, publication years, measure and elite athletes are the authors’ own moderator estimates, read from their accepted manuscript on PsyArXiv; its headline figures match the published abstract. The five groups overlap and are never added together, and ancestry describes the people studied, not countries.
Ambidextrous counts come from the UK Biobank and 23andMe cohorts in Cuellar-Partida and colleagues’ 2021 genetic study in Nature Human Behaviour, the two parts that offered that answer; we divide each published count by its cohort total. The study’s per-sex percentages for those cohorts do not match the cohort totals, so they are not used.
The group calculator is a binomial model: each person is left-handed with the chosen published rate, independently of everyone else. It reports the expected number, the chance of at least one, the range that 90% of such groups fall within, and a left-hander’s chance of being the only one. Real groups are not independent draws: handedness runs in families and some sports select for it.
Twins and multiple births
The twins page uses the CDC / National Center for Health Statistics report Births: Final Data for 2024 (National Vital Statistics Reports 75(2), June 2026): Table 12 for births by plurality in every year from 2010 to 2024 and by the mother’s race and Hispanic origin, and Table E for 2024 counts and the share born preterm. Twin rates by the mother’s age in 2014 and 2024 come from NCHS Health E-Stat 117. Both count live births, so “twins” are babies born in twin deliveries, and both are in the public domain. Every transcribed count reproduces the report’s published rates.
The reports count babies, not deliveries. For the odds per delivery we count each set once, dividing babies by set size, so a set in which a baby was stillborn is slightly undercounted; a twin rate by age becomes a share of deliveries as half the rate divided by 1,000 minus half the rate, treating every other baby as a single birth. These are approximations and are labelled as such. Birth certificates do not record whether twins are identical: the identical-twin rate of about 4 per 1,000 deliveries and the regional twinning rates (twin deliveries per 1,000 deliveries, 1980–1985 and 2010–2015) come from Monden, Pison and Smits in Human Reproduction (2021), a different measure that is never mixed with the U.S. rates per 1,000 births. The conjoined-twin rate, 1.47 per 100,000 births (383 sets among 26,138,837 births in 21 surveillance programs), is from the International Clearinghouse for Birth Defects Surveillance and Research study (American Journal of Medical Genetics Part C, 2011); the two semi-identical pairs are the case reports in Human Genetics (2007) and the New England Journal of Medicine (2019).
Adult weight
The average weight page transcribes Tables 3 (kilograms) and 4 (pounds) of the same CDC / NCHS Anthropometric Reference Data report that the height tools use (August 2021–August 2023, published June 2025, public domain): examined sample sizes, means, standard errors and nine percentiles for 16 groups by sex and age. Pregnant women are excluded by the report. Both units are kept exactly as published, and our build checks that each pound value matches its kilogram value within source rounding and that the age groups’ sample sizes add up to the all-adult row.
The percentile lookup interpolates linearly between adjacent published percentiles and rounds for display; below the 5th or above the 95th it reports only a bound. It uses the pound table for pounds and the kilogram table for kilograms. A percentile describes where a weight falls among measured adults of the same sex and age group; it is not a health assessment, and weights are never combined with other categories.
Net worth
The net worth page uses the Federal Reserve Board’s 2022 Survey of Consumer Finances summary extract (4,595 families, each recorded five times as “implicates” that fill in missing answers). Every statistic pools the five implicates with the file’s weights and takes the first value whose cumulative weight reaches the quantile. That method reproduces every 2022 median and average in the Board’s public-data Table 4, for all families and for six age groups, which we show as published; the build refuses to write if any differs. The 1st to 99th percentiles, the shares below zero and at $1 million or more, and the top thresholds are our computation from the same file by the same method, and the calculator interpolates between adjacent percentiles, with a bound below the 1st and above the 99th.
Families are the survey’s primary economic units, sorted by the age of a reference person; net worth is assets minus debts in 2022 dollars and excludes Social Security and defined-benefit pensions. The survey leaves out the Forbes 400. The public file is altered for confidentiality and omits 7 of the 4,602 interviewed families, so the Board’s Bulletin, based on internal data, differs slightly. Percentiles near the top of an age group rest on few families and carry more sampling error; we show the top 1% threshold only for all families.
Jobs
The jobs page uses the Bureau of Labor Statistics’ Occupational Employment and Wage Statistics national estimates for May 2025 (public domain): employment and annual wage percentiles for the 830 occupations BLS marks as detailed. Our build pins the published file, checks that their employment adds up to the all-occupations total within rounding and that pay percentiles never decrease, and writes one public file that the page and the lookup both read. Employment covers wage and salary workers in nonfarm establishments and excludes the self-employed, owners and partners in unincorporated firms, household workers and unpaid family workers; it is rounded to the nearest 10 and shown with the survey’s relative standard error.
“1 in N jobs” divides the all-occupations total by an occupation’s employment. Ranks count single occupations only; the “all other” residual groups, each several small jobs combined, are listed but not ranked. A pay comparison interpolates between an occupation’s published 10th, 25th, 50th, 75th and 90th percentile wages, and gives only a bound below the 10th or above the 90th; occupations published with hourly pay only get no annual comparison.
Birthday rankings
The birthday calculator uses 62,187,024 births over 5,479 calendar days, covering 2000–2014 inclusive. The underlying daily counts come from the U.S. Social Security Administration, as released in FiveThirtyEight’s births dataset. We use its SSA file alone. We do not combine it with the separate CDC 1994–2003 file, because the years overlap and the sources need not count exactly the same population.
For each month-and-day pair, we add every recorded birth on that date. A date’s “1 in N” value is 62,187,024 divided by its total recorded births. It describes the share of birth records in this historical sample. It does not estimate today’s living population or the probability of a future delivery on a specific date.
Rank #1 is the most common date. A rank equals one plus the number of dates with strictly more births, so any exact ties would share a rank. “Rarer than X% of other dates” counts dates with more births, divides by 365 other possible dates and multiplies by 100. This is a comparison of calendar dates, not a percentile of people. Figures are rounded for display; calculations retain their original precision.
Each result also has a plain-language verdict. It compares the date’s births per occurrence with the average day, 62,187,024 ÷ 5,479 = 11,350 births. Within 5% either way reads “About average” (275 of 366 dates); 5% or more above reads “More common than most”; 5–15% below, “Rarer than most”; more than 15% below, “One of the rarest” (December 25, January 1, December 24, July 4 and January 2). September 12 is the most common date, and February 29 the rarest overall because it occurs once every four years.
The birthday comparison uses the same total recorded birth counts as the main rankings. Its percentage difference is 100 × (larger count ÷ smaller count − 1). Leap day’s four occurrences remain in its total; the comparison does not normalize it to fifteen occurrences or claim a cause for the difference.
Births in 2024
The birth month page adds 2024 from the CDC / National Center for Health Statistics natality public-use file (public domain), one record for each of the 3,638,436 births registered in the U.S. that year. We keep the 3,628,934 births to U.S. residents, leaving out births to foreign residents as the official tables do, and count them by month, day of the week, hour of birth and method of delivery. Our build refuses to write unless those counts equal the published total and the vaginal, cesarean and not-stated counts in Table 9 of Births: Final Data for 2024 (NVSR 75(2)); the file’s SHA-256 is pinned. Births per day divide by the days each month or weekday had in 2024, a leap year that began on a Monday, so it had 53 Mondays and Tuesdays. Hours are the local time recorded on the birth certificate; 540 births had none. The public file has no day of the month, so every date ranking stays on the 2000–2014 records. The two periods are shown side by side and never combined.
February 29 and average births
You can reproduce these rankings from the 366-date CSV and printable heatmap. The table includes the count, number of occurrences, average per occurrence and full sample denominator for every date. It is a grouped reference derived from the daily source linked above.
Leap day occurs in 2000, 2004, 2008 and 2012 in this sample. Other month-and-day pairs occur fifteen times. The headline frequency keeps that difference: a randomly selected birth record is less likely to fall on a date that exists only four times. February 29 therefore has the fewest total records and rank #366.
The “births per occurrence” column answers a different question. It divides a date’s total by the number of times that date actually occurred: four for February 29, fifteen otherwise. February 29 averages 10,467 births per occurrence, which is not exceptionally low compared with some annual holidays. This conditional daily average must not be confused with its frequency across all birth records.
We do not silently replace leap day with February 28 or March 1, or assume every birthday has a 1-in-365 probability. The February table and rarest-birthday list make both measures available. The original file ends in 2014, so its ranking is not a claim about births in 2026.
The birthday heatmap can switch between total births and per-occurrence averages. Each view ranks its own measure; six equal-sized rank bands supply the color scale. A darker square means a higher value, rather than a fixed numerical gap between neighboring colors. The four lowest-ranked dates in the chosen view are purple instead: February 29, December 25, January 1 and December 24 by total births, and December 25, January 1, December 24 and July 4 per occurrence. The rank distribution uses that same chosen measure. Main result cards always use total births. The monthly chart divides each month's summed births by the number of observed days in that month across the whole sample; February includes four leap days. The infographic export prints its selected measure explicitly.
Rarity score, exact birthday, profile and twins
The rarity score is the “rarer than” percentage above, rounded to a whole number: the share of the 365 other dates with more recorded births. September 12 scores 0, May 14 scores 55 and February 29 scores 100. It orders calendar dates; it is not a percentile of people.
Your exact birthday uses a birth year if you add one. For 1994–2014 it shows the U.S. births recorded on that exact date and its rank among that year’s days, #1 being the busiest. The counts for 1994–1999 are CDC/NCHS birth-certificate totals and for 2000–2014 the SSA totals used everywhere else on this site, both from FiveThirtyEight’s births data (CC BY 4.0). A year never mixes the two: in 2000–2003, where both exist, SSA’s yearly totals are 1.8–2.2% higher and every single day’s count is higher, so ranks compare days within one year and source. The weekday chart averages that year’s births for each day of the week. Weekends and holidays are quieter mainly because planned inductions and cesarean births are scheduled on working days. For other years the result gives the weekday and the 2000–2014 weekday pattern.
The profile beside a birthday result names the sun sign from the zodiac counts below, with that sign’s rank among the twelve by total births. “Likely conceived” counts back 266 days (38 weeks), the typical time from conception to birth; real pregnancies vary by weeks either way. Birthstones follow the American Gem Society’s modern chart and birth flowers The Old Farmer’s Almanac’s list, both read on September 29, 2026. They are month traditions, not records. The countdown is worked out in the page from your device’s date; a February 29 birthday counts to the next leap year.
Birthday twins are well-known people born on the same month and day, from Wikidata (CC0), read on September 29, 2026. A person qualifies with an English Wikipedia article, articles in at least 30 Wikipedia language editions, a single Gregorian birth date recorded to the day, a birth year from 1800 on, and an occupation in entertainment, sport, the arts, writing or science. Politicians, military personnel, monarchs, political pundits and anyone with a recorded criminal conviction are left out, along with three serious criminal cases Wikidata had not yet recorded. For each date, the twelve candidates with the most language editions (U.S. citizens weighted 1.35 times) are ordered by English Wikipedia page views from September 2025 to August 2026, and the first six are shown. Wikidata can contain errors; the list is for fun and is not one of the site’s statistics.
Zodiac signs
The zodiac sign ranking uses the same SSA daily file, year by year rather than as 366 date totals, because the Sun reaches each sign on a slightly different date and hour every year. For every one of the 5,479 days, we compute the Sun's apparent geocentric ecliptic longitude (tropical zodiac, true equinox of date) at 12:00 noon U.S. Central Time with the open-source Astronomy Engine library, version 2.1.19, and count that day's births toward the sign the Sun occupied. Central Time sits near the middle of the U.S. population; the file records dates, not places or times of birth.
On 180 days the Sun changed sign during the Central calendar day. People born that day before and after the change have different signs, so those 2,063,416 births (3.3%) could belong to either neighbouring sign. The noon rule assigns each such day to the sign that held it at midday. As a check, splitting those births by the fraction of the day on each side of the change gives the same order for all twelve signs; that comparison is recorded in zodiac-provenance.json, not published as a second ranking.
A sign's share is its births divided by 62,187,024. "1 in N" is 100 divided by that percentage. Rank #1 has the most births. Births per day divides a sign's births by the number of days it held at noon across the fifteen years, which removes the effect of signs lasting 29 to 32 days. Verdicts compare each share with an even split of 1/12 (8.33%): the most and least common signs are named, shares at least 4% above or below the even split read "more common" or "rarer than most", and the rest read "about average".
"Usual dates" are the dates on which a sign held noon in most of the years that date occurred. The birthday finder reports the sign at noon in most years; if the Sun changed sign on that calendar date in any year, it says in how many of the fifteen (four for February 29) and names both signs. It cannot resolve a cusp birth without the year, time and place. The ranking describes U.S. births from 2000 to 2014 only. It is not a worldwide or current estimate and makes no astrological claim.
Birthstones
The birthstone chart follows the official list of Jewelers of America, which created it in 1912, read on October 11, 2026. Bloodstone (March) and sardonyx (August) appear as also listed because the American Gem Society and GIA list them and Jewelers of America does not. Colors shorten GIA's descriptions of each stone; the gem icons are illustrations, not measured colors.
Everyone born in a month shares its birthstones, so a stone's share of people is its month's share of births: the month's births divided by all 62,187,024 in the SSA 2000–2014 file, the same counts as the month pages. "1 in N" is 100 divided by that percentage, and rank #1 is the month with the most births. The 2024 column uses the natality file's 3,628,934 births to U.S. residents; the two periods are never combined. A stone listed for one month only gets that month's share; no stone appears in two months on these lists. Gem rarity is quoted from GIA's birthstone pages and gem encyclopedia as published. GIA does not rank birthstones by rarity, so the site does not either.
First names
The first-name lookup uses the SSA national baby-name data, with birth years 1880–2025: SSA’s own national file from the release with 2025 data, announced on May 8, 2026 (2,181,032 rows, 105,966 spellings). SSA’s server refuses command-line downloads, so the unmodified ZIP was saved through a browser on September 29, 2026; its SHA-256 is pinned and checked on every rebuild. SSA revises earlier years slightly with each release (the 2024 total rose from 3,328,501 to 3,343,078), so all years come from this one release. Earlier versions of this site used the previous release through a public mirror pinned to one revision. We import only the original data files, then calculate our own counts and rankings.
For a selected year, female and male published counts are combined for each spelling. The denominator is the sum of those published counts, not the number of all births. SSA suppresses low-frequency entries within each sex category and year. The withheld records cannot be reconstructed here, so a “1 in” result describes released name records only. A missing spelling returns no estimate, rather than a zero or an invented one-person count.
SSA explains that early records are incomplete and that the data arise from Social Security card applications; see its background notes. These are birth-year cohorts, not a census of people alive today. Rank is one plus the number of combined spellings with higher published counts. Results also give the spelling’s rank on SSA’s own female or male list, computed the same way within that category, because that is how SSA publishes its popular names; a second list appears when it holds at least a tenth as many records. Verdicts use those list ranks (top 10, 100 or 1,000) or, beyond SSA’s top 1,000, the combined count (fewer than 25 or 100 babies). A spelling with no published count that year is shown as below SSA’s threshold of five babies per category, never as a zero or a unique name. Every SSA spelling uses 2–15 capital letters A–Z, with no accents, spaces or punctuation; longer names appear with their first 15 letters. Typed names are matched the same way, with accents reduced to base letters (José → JOSE), and the result shows how the file writes the name. Alternative spellings remain separate. The result does not infer a person’s sex, ancestry or identity.
The name comparison chart expresses each selected-year count per 10,000 published records: 10,000 × name count ÷ published total for that year. It shows 1960, 1980, 2000, 2025 and the lookup’s selected year without duplicate years. An absent spelling remains unknown and gets no bar. These selected cohorts do not establish an all-time peak or a continuous trend. The expandable table exposes the counts and denominators used.
The separate popularity history applies that formula to all 146 annual files. Lines break at missing counts rather than interpolating through them. Highest and lowest shares are selected only from years with published counts; exact ties show the earliest year. No result treats an absent year as zero. The slider, complete count table and exported chart all use the same normalized series. The original records support the historical published series, not an estimate of everyone alive with a name.
An optional second spelling shares the same chart scale and each year’s denominator. The selected-year ratio compares counts only when both names have a published count; a missing name is never the rarer one by default. Two inputs that normalize to the same spelling refer to one source entry. The downloadable CSV keeps a blank count and rate for unpublished years, an explicit publication-status field, and the source spelling rather than a typed label. It is generated on the device for one or both names.
The name explorer retains the original female and male source counts. A missing category stays unknown. For combined results, only published counts are summed. Female and male filters rank within the selected category; the “both categories” filter keeps combined ranks but requires a published count in each category. Ranks are calculated before prefix, length or count filters, with equal counts sharing a rank. Spelling breaks display-order ties. These are our count-based ranks; SSA’s own category lists can order tied names differently.
“Lowest published counts” cannot identify names hidden below SSA’s threshold. Random suggestions sample actual rows matching the filters and imply no compatibility, name meaning or personal identity. Name Duel compares the two combined-category counts in the same year, using their larger-to-smaller count ratio and that year's shared published denominator. It refuses a comparison when either spelling is absent.
Names by place
The 2025 name comparison keeps the SSA U.S. file and ONS England and Wales annual Table 6 separate. The denominator is the sum of published counts in that place’s selected female or male category: it is not all births or a living population. Rates equal a name’s count divided by that sum, multiplied by 10,000. Withheld counts remain unknown, including when a spelling appears in the other place.
ONS girls’ and boys’ annual tables were released on July 9, 2026. Table 6 excludes unstated names and mothers usually resident outside England and Wales; counts below three are withheld. The complete download preserves source ranks as published metadata; frequencies are calculated from counts. SSA uses its separate five-record threshold. We do not pool these populations or derive worldwide name counts.
ONS keeps punctuation that SSA removes. The ONS match ignores letter case, folds accents and typographic apostrophes/hyphens, and preserves the resulting spelling without truncation. SSA uses the source-key rules above. Different resulting spellings receive no comparative rarity label. The typed name never enters a request, URL or browser storage: every comparison loads the same two public files. Contains public sector information licensed under the Open Government Licence v3.0.
First-name census
The 2020 first-name lookup uses the Census Bureau’s first-name by-sex workbook, released April 14, 2026. We retain only the spelling, combined count and official rank. The full file and its separate top-1,000 workbook agree. All 53,615 named rows sum to 283,236,830, plus 18,794,706 in ALL OTHER NAMES, for 302,031,536 recorded first names. Rates divide the published count by that total; the unlisted aggregate is included but unranked. This denominator excludes missing and unusable responses and is not the full census population.
The Census first-name brief, pages 2–3, describes privacy adjustment and editing. A name had to occur at least 100 times in both the 2010 and 2020 confidential census files before noise was added. The public by-sex table contains 155 names with adjusted totals below 100; Doglas and Jesue have 91 each and share rank 53,614. Absence does not establish zero, a current total or even a below-100 count in 2020. No public 2010 first-name table is available for a historical comparison.
Noise was added separately to each sex cell, followed by optimization to remove negatives; the displayed total is their sum. The brief’s ±4 probability statement applies to individual sex cells, not a combined-name confidence interval. The race/Hispanic-origin table was adjusted independently: 49,089 named counts and 50,700 ranks differ, and its denominator is 302,029,327. That is also the brief’s Table 1 total. We never mix that denominator or those ranks with the by-sex counts.
Names are matched using A–Z letters, folding accents and removing spaces, apostrophes, hyphens and periods. We do not guess the Census Bureau’s spelling corrections, suffix deletions or truncations. The workbook’s longest published key is 13 letters; an absent longer spelling remains unknown, rather than being shortened to a different name. Counts may retain some generic text or transcription errors after source editing.
The complete CSV preserves every named record, source rank and the unlisted aggregate. The personal CSV retains unknown numeric cells as blanks. Lookups use one identical public file for everyone and keep names on the device. Neither Census counts nor their ratios to SSA births establish today’s population, migration, ancestry, a full-name count or a personal identity.
Living Americans
Beside the recorded counts, the first-name result gives a model estimate of living Americans who share the spelling. It is not a count from any census. We follow the method FiveThirtyEight published in 2014 (Nate Silver and Allison McCann, “How to Tell Someone’s Age When All You Know Is Her Name”, May 29, 2014): for every birth year from 1900 to 2025 and each SSA sex category, multiply the published count for the spelling by the share of that birth-year cohort still alive, then add the years together.
The survival shares come from the Social Security Administration’s cohort life tables for the 2026 Trustees Report, Alternative 2 (the intermediate assumptions), by sex and single birth year. For a cohort born in year y, the share alive at mid-2026 is the table’s survivors at exact age 2026 − y divided by its 100,000 births. Cohorts before 1900, which the tables do not cover, and anyone past the tables’ last age count as zero. For example, 71.362% of women born in 1950 and 95.381% of men born in 1990 are expected to be alive, so 100 girls from 1950, 50 boys from 1990 and 10 girls from 2025 (99.469%) contribute about 129 people.
The model assumes that people with a name die at the same rates as everyone of their sex and birth year, though survival differs by group, and names can follow those differences. It counts only U.S.-born people whose births appear in SSA’s Social Security card records: it ignores immigration and emigration, spellings below SSA’s publication threshold (five babies per sex per year) and name changes. Birth records before the late 1930s are incomplete. Treat the figure as an order of magnitude, rounded to two significant figures, beside the recorded counts it is built from. Evelyn, for instance, is about 310,000; the modelled total across all spellings is about 272 million.
The most common names page sums the same model over every published name and sex: its living lists rank names by that estimate, and its all-time and decade lists are exact sums of the published births. The build refuses to write unless its totals reproduce the lookup’s own estimate for every name, so the page and the lookup always agree.
Rare first names
The rare names page uses the same Social Security files as the name tool, 1880–2025, and exact counts only. Social Security lists a name for a sex and year only when at least five babies get it, so every list is limited to names that reach that floor. Rare for a century means a name listed for a sex in every year from 1926 to 2025 (958 girls’ names and 1,155 boys’ names) and never given to more than 50 babies of that sex in a year: 18 girls’ names and 42 boys’ names. Popular names that became rare are names in the top 100 for their sex in at least one year, ranked the way Social Security ranks its own lists (one plus the number of names given to more babies of that sex that year, so ties share a rank), that went to fewer than 100 babies of that sex in 2025; a name missing from 2025 went to fewer than five. The floor figures count 2025 names at exactly five babies. Girls’ and boys’ counts are never combined on this page. tools/ builds every list and checks Debra (#2 in 1956) and Minnie (#5 in 1880) against Social Security’s published rankings.
Historical name profiles
The name profile sums a spelling’s published annual counts across the pinned 1880–2025 release. Its historical count rank equals one plus the number of spellings with a strictly larger sum. The total includes only published records from both SSA source categories, not withheld counts. It is not a count of people currently alive: these files do not measure survival, migration or later name changes.
The first and last published years are the earliest and latest entries with a count in this release. They do not establish the name’s origin, first use or disappearance. The largest annual count is a raw-count maximum, with the earliest year shown on a tie; the popularity-history maximum instead uses the annual share. Those two peak years need not match.
Each decade adds its known counts. Its percentage is 100 × decade’s published count ÷ spelling’s total published count. A wholly unpublished decade remains unknown, with no zero-frequency claim. Partly observed decades sum only their published entries. The final period, 2020–2025, is a partial decade. These bars describe the historical records and cannot establish the age distribution of living people. Early-source incompleteness also limits comparisons across decades.
The example profile, historical top-20 table, interactive profiles and downloadable fact sheets use the same calculations. A–Z browsing and alphabetical ordering filter the existing annual name explorer; they never recalculate count rank within a letter or publish a separate page for every spelling.
Surname census years
The 2010–2020 surname comparison uses the existing 2010 Census table and the Census Bureau’s 2020 names release, published April 14, 2026. The full 2020 workbook was modified May 14, 2026; its first 1,000 rows agree with the separate top-1,000 workbook. We retain only spelling, total count and source rank. The 2020 full CSV includes all 156,621 named rows and the “all other names” aggregate.
Each frequency is 100,000 × published count ÷ that census’s recorded-surname total: 294,979,229 in 2010 and 298,898,231 in 2020. The latter reconciles to 262,640,594 named records plus 36,257,637 other records. Missing surname records are outside both denominators. The 2020 workbook’s per-100,000 and cumulative proportions reproduce these calculations; ranks retain the source’s ties. Its total matches the final total in Table 1 of the 2020 Census brief. Table 1’s frequency-band subtotals are not substituted for the workbook.
The 2020 brief describes an inclusion rule of at least 100 records in both censuses, then privacy noise applied to demographic cells and an optimization step removing negative counts. Published surname totals are calculated from those adjusted cells. Consequently, 617 published counts are below 100, with Drewno at 92. The brief’s noise probability of at least 95% within ±2 describes an individual demographic cell; it is not a confidence interval for a surname total. We do not import demographic fields or infer anyone’s ethnicity.
One public-file exception needs care: NA appears in the 2020 workbook with 20,876 records but has no entry in the original 2010 Census ZIP. We keep its 2010 count unknown and provide no count-change calculation. Another 5,633 spellings in the public 2010 file are absent in 2020. Absence never becomes zero, an extinction claim or a precise upper bound.
The difference and percentage change are arithmetic comparisons of the two published counts. Nonresponse coverage, editing rules and privacy methods differ; the change is not an exact population-growth estimate or a significance test. Both files contain A–Z spellings of at most 15 letters, so this tool follows the existing surname spelling rules. The example and reference table are native HTML. Personal comparisons fetch identical public files for everyone, keep inputs in page memory and export two rows with blank missing counts and source context. The older lookup, atlas, two-surname comparison and cards remain explicitly about 2010.
Surnames
The surname table comes from Frequently Occurring Surnames from the 2010 Census. It publishes 162,253 surnames with at least 100 recorded occurrences. We retain the spelling, count and official rank; demographic percentage columns are not used by this product.
We divide 294,979,229 recorded surname entries by the surname’s count. That denominator includes the source’s “all other names” aggregate of 29,312,001, covering names below the publication threshold. It does not include people without usable surname records. The Census’s technical documentation, table 1 explains the coverage and editing rules. Verdicts follow the official ranks (top 100, 1,000 or 10,000) and, beyond that, the published count (fewer than 200 or 1,000 people). An absent spelling is shown as below the 100-person publication threshold; its exact frequency stays unknown. The tool does not estimate current counts, family relationships or a name’s country of origin.
The surname explorer preserves official Census ranks before prefix or count filters. It sorts equal counts by source spelling and paginates every matching published row. “Exactly 100” refers to the smallest released count, not an estimate for names below the threshold. Matching follows the table’s own spelling rules: capital A–Z only, punctuation and spaces deleted, at most 15 letters (the published file contains no other form). Accents therefore reduce to base letters, so Muñoz matches MUNOZ, and the result says so. Alternative spellings are never guessed.
The surname comparison uses 10,000 × surname count ÷ 294,979,229 for each rate and the larger count divided by the smaller count for its ratio. Same-spelling and equal-count cases are labeled explicitly. If either spelling is absent, no ratio is produced.
The surname atlas sums five disjoint official-rank bands: 1–10, 11–100, 101–1,000, 1,001–10,000 and 10,001 onward. The sixth band is the below-threshold aggregate. All six sum exactly to the recorded-surname denominator. Bar lengths and printed percentages use the original counts. The 100-square illustration rounds shares down first, then assigns leftover squares to the largest fractional remainders; source-order breaks a tie. This keeps exactly 100 squares without changing any count. Each square is an approximate percentage point, not an individual name.
Languages
The language rarity tool uses the Census Bureau’s detailed 2017–2021 ACS language table, released in June 2025. It includes 566 language and group entries, including English only at home: 481 detailed categories and 85 broader group rows. These are published categories, not a count of distinct world languages. The table’s age-5-and-over U.S. population estimate is 310,300,000. The English-only estimate is 243,100,000; the other-language estimate is 67,200,000.
The population refers to U.S. residents, not only citizens. It describes language reported at home, not every language a person knows, their native language, or worldwide fluency. The five-year estimate represents 2017–2021, not five populations added together. English-only excludes people reporting another language at home even if they also speak English. Missing languages receive no estimate, and signed-language use is not separately measured by this tool.
Each share is 100 × published category estimate ÷ 310,300,000. “About 1 in” is the reciprocal, rounded to two significant digits. Percentages have at most three significant digits. Count estimates and their 90% margins of error are retained exactly as published. Where the margin of error is at least the estimate, the main result and share card replace the percentage with an uncertainty message. We do not derive a confidence interval for the ratio from these counts.
Source spreadsheet indentation preserves each parent group and its children. Groups overlap descendants; the lookup tool never sums them, mixes their ranks, or treats a group as a single language. A detailed category can exclude responses recorded under a broader or separately named variety. Counts follow the source’s classifications, including unspecified categories. Counts are rounded independently by Census, so children need not add exactly to a published subtotal. The downloadable CSV retains all original labels and source-row identifiers.
Comparisons show both estimates, margins of error and shares of the same population. The larger-to-smaller count ratio describes point estimates only. Parent/child comparisons are explicitly marked as overlapping. An overlap between the two count intervals is flagged for uncertainty; neither overlapping nor non-overlapping intervals replace a formal significance test. No combined multilingual odds or worldwide rarity rank is calculated.
The overview’s 100 squares round the English-only share to 78 squares and assign 22 to other home-language use. Each square represents roughly one percentage point, not an individual respondent. The six example bars in the printable infographic compare their counts on one scale. The on-page table selects 20 large terminal categories, omitting each category’s own parent subtotals. These examples do not form a complete language census. Cards preserve the category type, population, period, estimate and margin of error in both image formats.
The national language chart ranks languages with their varieties counted together, because that is how people ask the question. Where the Census groups a language with its varieties under that language’s own name, meaning a group row with a detailed row of the same name beneath it (Chinese with Mandarin, Yue and others; Tagalog with Filipino; Arabic, French, German, Hindi, Italian, Portuguese, Haitian, Persian and a few more), the group is ranked in place of all its rows. Every other branch uses its terminal categories, the rows with no more detailed children. So no ranked row contains another, and 436 rows cover all other-language use (their published counts sum to 67,205,828 against the independently rounded 67,200,000). Families of different languages, such as Slavic languages, and residual groups such as “Other and unspecified languages” never count as one language. English-only appears separately. The table shows the largest fifteen. One CSV has all 436 languages and what each group includes; a second keeps all 486 terminal categories on their own, the ranking this page used until September 30, 2026. Ordering is by point estimate, with source identifier breaking display-order ties; it is not a statistical significance ranking. The French profile explicitly separates the detailed row, its sibling and their broader group.
Languages by state
The state explorer uses Table 2 of the same Census release, covering all fifty states and D.C. Each profile retains the published population age 5+, English-only and other-language estimates, and the fifteen largest reported non-English categories. Category labels and 90% count margins of error come directly from the original state workbook. A category missing from a state's top fifteen remains unknown; national proportions never fill that gap.
State percentages are 100 × category estimate ÷ that state's age-5+ population estimate. The population's own margin of error is shown separately. We do not calculate percentage confidence intervals or force independently rounded totals to add. The chart orders the published point estimates; differences between nearby ranks may not be significant.
The alphabetical heatmap colors the share reporting a language other than English at home: below 10%, 10–under 20%, 20–under 30%, 30–under 40%, and 40% or more. Every tile has its numerical share. It is not a geographic map. Selected-state chart bars compare counts with that state's largest displayed category, so bar lengths across separate state charts do not share a common count scale.
The full state CSV retains 867 rows: fifteen categories plus two home-language aggregates for each of 51 jurisdictions. Parent aggregates and individual categories must not be added together. State selection and its generated SVG stay on the device; public overview files contain no personalized choice. French state examples reproduce the state table's French category and are not a complete ranking of states.
Cards, licensing and corrections
Cards preserve the population and year for each result. A combined card contains separate facts, with no multiplication of probabilities. First names, surnames and birthdays may be associated with one another, and these files do not describe the same population. Treating them as independent would manufacture a precision the data do not support.
FiveThirtyEight’s compiled data are supplied under Creative Commons Attribution 4.0. We aggregate and rank the counts, attribute the compilation on birthday results, and link this methodology on every image. SSA and Census data are U.S. government statistical releases. No agency endorses this site. The charts and card artwork are our own.
Found a calculation or source problem? Contact us with the page, dataset year and steps needed to reproduce it. Please do not send someone else’s personal information. A correction should change the calculation and every affected display together, rather than leaving old cards or tables inconsistent with the source.
Car models
The separate UK manufacture-year breakdown reads both halves of DfT’s VEH0124 annual file, taking only Cars at 31 December 2025. It sums recorded variants and first-use years within each exact make, generic model, manufacture year and licence status. The 550,903 retained source rows yield 35,086 year rows in 2,908 groups; 408 missing-model groups remain in the complete download but not the chooser. Counts are all published integers in this snapshot. Unknown manufacture year stays unknown, with its 160,602 licensed and 92,049 SORN cars retained in denominators.
Both status totals match VEH0120 for December 2025 exactly: 34,485,453 licensed and 4,004,932 SORN. Individual model groups do not always match, because DfT revises their definitions between releases. We keep the annual groups separate and do not apply quarterly variants or denominators to them. Shares use the selected annual group’s licensed total, not licensed plus SORN. Original files and hashes, source encoding, row totals and differences are pinned in the data build. Unusual recorded years remain visible; they are not verified production dates. The complete CSV carries the snapshot, UK geography, source and Open Government Licence attribution.
The car rarity lookup uses the Department for Transport's VEH0120 UK CSV, released 23 September 2026. It retains the Cars rows from September 2014 through June 2026: 2,838 model groups and 52,244 recorded variants. Licensed and SORN counts remain separate. The denominator on the latest result is all 34,888,140 licensed UK cars, including missing-model records. This UK reference does not measure U.S. cars or worldwide production. The separate U.S. option is described below.
Fuel rows are added within their exact make, model group, model and licence status. Every quarter reconciles across the original rows, generated model groups and variants. The 417 groups with missing model details remain in the denominator and downloadable CSV, but are excluded from named-model search and ranking. Tied licensed counts share rank. Missing search results get no count; published zero means zero recorded in that cell, not no surviving cars.
Percentages are licensed model counts divided by that quarter's licensed-car denominator. Approximate one-in frequencies invert that share. The displayed change compares the same quarter a year apart; a zero previous count has no percentage change. A group and its variant overlap and must not be added. DfT's definitions and data limitations explain licensing, missing codes and administrative revisions. Figures are not valuations, condition assessments or scrappage rates.
The lookup, history, comparison and local card use the same retained source. Original charts and exports credit DfT / DVLA and retain the UK period. Contains public sector information licensed under the Open Government Licence v3.0.
Washington plug-in vehicles
The U.S. option in the car tool uses Washington DOL’s Electric Vehicle Population Data: 299,705 distinct vehicles, 202 models, 785 model/year/powertrain combinations, as of 31 August 2026. The source was updated on 15 September. It includes BEVs and PHEVs registered through Washington DOL, even when their owners have out-of-state addresses. It is neither a national U.S. fleet nor all cars in Washington.
Counts are aggregated by exact make, model, model year and powertrain, then reconciled to a separate source query grouped only by model. Every share uses the full plug-in denominator, including when one model year is selected. Whole models receive a rank with ties shared; individual years do not. Year bars describe the composition of this snapshot, not a time series of past fleet sizes. Missing models or years cannot establish a zero count outside the published reference.
The complete derived model-year database is freely available under the source’s Open Database License 1.0. The UK and Washington populations remain separate and are never combined into an estimate. No VINs or owner locations are imported.
Dog names
The dog name generator and frequency lookup uses the NYC DOHMH Dog Licensing Dataset, filtered to extract_year 2026, published 15 July 2026. Its 96,459 license-period records can include repeated renewals for the same dog. We do not label the records unique dogs or a complete calendar-year census.
We aggregate name and recorded sex, normalize case and repeated spaces, and preserve punctuation and accents. There are 14,658 retained name spellings. The 2,879 records labelled blank, UNKNOWN, NAME NOT PROVIDED or NONE are excluded from name rankings, but stay in the denominator and full CSV reconciliation. Name counts reconcile to a separate source query without the sex grouping. The spelling with the most records is #1; ties share a rank. A missing spelling is unknown.
Suggestions use spellings of 2–24 characters made from Latin letters, spaces, apostrophes and hyphens, with at least three records. Uncommon means 3–10 records; popular means at least 100. A sex filter requires at least one record in that category, while the displayed frequency remains the combined count. Random suggestions sample matching spellings equally without replacement. These filters are browsing choices, not scientific rarity classes or claims about name origins.
Only aggregate names and counts are imported. Owner ZIP codes, individual dog birth years and licensing dates are not part of this tool. The complete CSV and original chart retain the source and extract label.
Income percentiles
The income percentile calculator tabulates the U.S. Census Bureau’s 2026 CPS ASEC public-use file: income received in 2025, with people and households as of March 2026. build_income_percentiles.py verifies the file’s SHA-256 and builds three populations, each for all ages and twelve age groups from 15–24 to 75+:
- Households: 53,344 interviewed households, weighted to 137.1 million, by total household money income and the age of the householder (the reference person). The household weight equals the householder’s person weight on every record, so household margins use the householder’s replicate weights.
- People with income: 96,720 people aged 15 and over whose total money income was not zero, losses included, weighted to 248.3 million: PINC-01’s “total with income”.
- Full-time, year-round workers: the 48,159 of them who worked full time for 50 to 52 weeks, weighted to 124.0 million.
For each group the build adds the survey weights below every multiple of $2,500 up to $2.5 million, and a percentile interpolates in a straight line inside its interval, the method behind the Census Bureau’s published medians. Each share’s standard error uses the 160 successive-difference replicate weights, variance = 4 ÷ 160 × Σ (replicate − full)²; the calculator shows 90% margins (1.645 standard errors). A cutoff appears only with at least 30 respondents above it; a rank stops at the highest such percentile, and at the bottom of a small group at the lowest percentile with 30 respondents at or below it.
The build refuses to write unless it reproduces the published tables: group totals within 0.3% of HINC-02 and PINC-01 (the largest gap is 0.16%), the share below every published income band edge within 0.3 percentage points (largest 0.26), and every median within twice its published standard error or 0.5% (largest gap $270, for householders aged 35–39). All households: $87,390 against the published $87,460. People with income: $46,950 against $46,960. Full-time, year-round workers: $70,970, exactly as published.
In the public file, amounts above the Census swap thresholds (earnings above $458,000, among others) are exchanged between respondents of similar rank and rounded to two significant digits; the technical documentation says the distribution above each threshold is preserved. Comparisons do not adjust for household size, geography, living costs or inflation. The household heatmap and the 533-row band CSV keep the published HINC-02 counts with their disclosure rounding (137,059,000 across the national bands against a published 137,100,000). The percentiles CSV has percentiles 1 to 99 for all 39 groups, with standard errors and respondent counts. Inputs and personal cards are processed locally.
Your type
The type calculator tabulates the U.S. Census Bureau's 2026 CPS Annual Social and Economic Supplement public-use file: 103,285 adults aged 18 and over, weighted to 266,472,300 people (128,732,351 men and 137,739,950 women) living in households in March 2026, with their own money income for 2025. build_type.py verifies the file's SHA-256, then precomputes all 61,152 combinations the calculator offers: men, women or anyone; 91 age ranges built from thirteen bands (18–20, 21–24, then five-year bands to 70–74, and 75+); four relationship filters; seven education floors; eight income floors.
Each estimate sums the ASEC person weight (MARSUPWT, equal to replicate weight 0). Its standard error uses the 160 successive-difference replicate weights: variance = 4 ÷ 160 × Σ (replicate − full)², the method the Census Bureau's 2026 source-and-accuracy statement prescribes in place of the older generalized variance parameters. Margins shown are 90% (1.645 standard errors). The build reproduces that statement's person-level illustration exactly (14,360,000 U.S.-born New York residents, standard error 169,000) and reconciles its own counts with the published PINC-01 tables for men and women by age band and for bachelor's degrees, in total and at $100,000 or more: all 48 cells agree within 0.23%, the size of the public file's disclosure edits.
Definitions: married means married with a spouse present or absent; not married means never married, divorced, widowed or separated; single means not married and with no cohabiting partner recorded in the household; never married includes people living with a partner. Education floors follow the highest degree reported, with professional degrees and doctorates grouped. Income is total personal money income received in 2025 before taxes, from all sources, including losses; "$100,000 or more" is inclusive.
Shares divide an estimate by all adults 18+ of the chosen sex (or all adults). "1 in N" is 100 ÷ share, rounded (to the nearest ten from 100). A combination matched by fewer than 30 respondents shows no estimate: that is a reliability limit, never a zero. The step list adds one criterion at a time in a fixed order; "of the step above" divides consecutive estimates. The comparison with multiplied shares multiplies each chosen criterion's share of the whole group, the shortcut viral calculators take, to show how much the traits overlap. No race, height, weight, children or location filters: height is not in this survey, and the site does not combine surveys.
Pennies
The rarest pennies page ranks Lincoln cents made for circulation by mintage, the number struck, and its lookup gives the figure for one date and mint mark. build_coins.py publishes a figure only when a U.S. Mint document or the Mint’s own year-end report stands behind it:
- 1909–1965: the Mint’s record. The Bureau of the Mint’s Domestic and Foreign Coins Manufactured by Mints of the United States, 1792–1965 lists cents struck each calendar year at Philadelphia, Denver and San Francisco. We read the three columns from the page images. The Denver and San Francisco columns must add up to the totals the Mint printed (21,010,677,400 and 2,953,795,004), and 1943 must add up to the 1,093,838,670 steel cents the same book reports. The Mint counted proofs with Philadelphia’s cents in some years, so each year must equal the collectors’ business-strike figure or that figure plus the year’s proofs. Coins dated 1964 and 1965 were struck across calendar years; the Mint’s own tables of coins bearing those dates give 2,648,575,000 cents dated 1964 without a mint mark (196,630,000 of them struck at San Francisco) and 3,799,071,500 from Denver.
- 1999–2025: the Mint’s production reports. usmint.gov’s annual production page for each year, as archived by the Internet Archive after the year ended, or where no such capture exists (2012–2015, 2018, 2024, 2025) the Mint’s year-end figures as CoinNews reported them each January. Where both exist they must agree.
- 1966–1979: the Mint’s annual reports. Each annual report of the Director of the Mint through fiscal 1980 has a table of coins made in the calendar year by mint, and the fiscal 1971 report counts the coins dated 1966. We read those tables from the page images; each year’s rows must add up to the total printed. Cents struck without a mint mark at West Point (from 1974) and San Francisco (1978 and 1979) count with Philadelphia’s, as the standard references count them. A figure is published only where it equals the collectors’ figure for the date, or that figure less the special mint sets the report counts apart, or where the report shows the collectors’ figure is wrong.
- 1971 and 1980: the Mint’s 1981 record. The Bureau of the Mint’s Domestic and Foreign Coins Manufactured by Mints of the United States, 1793–1980 (1981) lists cents made each calendar year at each mint, the same way. It agrees with every annual-report figure it repeats. Its Denver and San Francisco columns add up to the totals it prints (73,879,802,257 and 9,775,654,120), and San Francisco’s count includes that year’s proofs, which are taken off.
- No figure: three San Francisco issues and 1981–1998. For the San Francisco cents of 1972, 1973 and 1974 the report’s figure is larger than the collectors’ by exactly that year’s proofs, and the 1981 record repeats the report, so neither is used. The Mint’s reports from fiscal 1981 on count fiscal years, not the date on the coin. For these the lookup gives only the size of the mintage, billions or hundreds of millions, and the download leaves the figure blank.
The 1909 issues with the designer’s initials (V.D.B.) are the one split the Mint’s record does not make: it counts all 1909 cents together, Indian Head cents included. The collectors’ figures of 27,995,000 and 484,000 add up to the Mint’s totals once the 1909 Indian Head cents are counted.
The widely copied compiled table of mintages (the revision we compared) disagreed with a Mint source in twelve figures, among them 1944 (1,435,000,000 for the Mint’s 1,435,400,000), 1945-D (266,268,000 for 226,268,000), 1977-D (4,194,062,300 for 4,149,062,300, which the report’s face value of $41,490,623 confirms), 2004 (Philadelphia and Denver swapped), 2010-D (2,407,200,000 for 2,047,200,000) and 2015 (short by 476 million). The Mint’s figure is used in each case, and coins-provenance.json lists all twelve.
Ranks run from the lowest mintage and are shown below 100 million, where no unchecked year can change them. The total of about 560 billion Lincoln cents, the decade chart and “1 in” shares are rounded, because about two-fifths of the total rests on the unchecked years.
Metal: cents before 1982 weigh 48 grains (3.11 grams) and are 95% copper, and 1943 cents are zinc-coated steel, per the same Mint record; cents since 1982 are 2.5 grams of copper-plated zinc (97.5% zinc), per the Mint’s coin specifications. Metal values use the World Bank’s monthly average copper and zinc prices (Commodity Price Data, August 2026: copper $14,326 and zinc $3,875 a tonne). They are the value of the metal, not an offer anyone makes; melting cents is barred by 31 CFR Part 82.
Counts of known error coins (1943 bronze, 1944 steel, the doubled dies) are collectors’ censuses, and sale prices are single auction results, each linked on the page. They are not valuations. The lookup runs on the page from one public file; the year and mint mark you choose are not sent anywhere.
Quarters
The rarest quarters page ranks Washington quarters made for circulation by mintage, and its lookup gives the figure for one date, mint mark and design. build_quarters.py follows the penny rules: a figure only where a U.S. Mint document or the Mint’s own year-end figures stand behind it.
- 1932–1965: the Mint’s record. The same Bureau of the Mint record lists quarters struck each calendar year at Philadelphia, Denver and San Francisco; its Denver column must add up to the total the Mint printed, and each year must equal the collectors’ business-strike figure or that figure plus the year’s proofs. Quarters dated 1964 and 1965 come from the Mint’s tables of coins bearing those dates: 560,390,585 dated 1964 without a mint mark (19,870,585 of them struck at San Francisco in 1965), 704,135,528 from Denver, and 1,817,357,540 dated 1965 from all three mints, not counting 2,360,000 special mint set coins sold to collectors.
- 1999–2025: the Mint’s figures for each design. usmint.gov’s production pages for the 50 State, District of Columbia and Territories, and America the Beautiful programs, archived by the Internet Archive after each program year ended, cover 1999 to 2016 and the 2021 Tuskegee Airmen design; the Mint’s year-end figures as CoinNews reported them cover 2017 to 2025. Where both exist they agree to the coin. The 2019-W figure, two million of each design, is from the Mint’s 2019 annual report.
- 1966–1979: the Mint’s annual reports. The same calendar-year tables as for the penny, read the same way. Quarters struck without a mint mark at West Point from 1976 on count with Philadelphia’s.
- 1971, 1974, the Bicentennial and 1980: the Mint’s 1981 record. The same 1793–1980 record lists quarters by mint and calendar year, and its footnotes say how many of each mint’s 1975 quarters bore the Bicentennial date: 438,720,000 at Philadelphia and 377,848,000 at Denver. The rest were dated 1974. So 801,456,000 quarters dated 1974 come from Philadelphia and 353,160,300 from Denver, and the Bicentennial quarters number 809,784,000 and 860,118,839. Together those are the 1,669,902,839 the Mint reported in 1977.
- No figure: 1981–1998 and 2020-W. The later reports count fiscal years. The Mint published no count of the 2020-W quarters that we could find.
The compiled table most sites copy has 15,388,000 for the 1947-D, where the Mint printed 15,338,400. It has 518,708,000 for the 1979 Philadelphia quarter, where the Mint’s report and its 1981 record have 515,708,000 with West Point. It has 809,784,016 for the Philadelphia Bicentennial quarters, 16 more than the Mint’s record adds up to. It also adds the special mint sets to its 1965 and 1966 totals. The Mint’s figure is used, and quarters-provenance.json lists the five corrections. Ranks run from the lowest mintage and are shown below 100 million, where no unchecked year can change them; the five 2019-W designs share a rank.
Metal: quarters of 1932 to 1964 weigh 96.45 grains (6.25 grams) at 900 fine, 0.1808 troy ounces of silver; from 1965 they weigh 5.67 grams, copper-nickel faces on a copper core (8.33% nickel overall), per the same Mint record and the Mint’s coin specifications. Metal values use the World Bank’s monthly average prices (Commodity Price Data, August 2026: silver $65.40 a troy ounce, copper $14,326 and nickel $16,751 a tonne). The cost of making a quarter, 14.53 cents in fiscal 2025, is from the Mint’s 2025 annual report.
Record prices are single auction results for the finest coins, each linked on the page. They are not valuations. The lookup runs on the page from one public file; the year, mint mark and design you choose are not sent anywhere.
Additional trait and breed references
The personality-type tables retain the MBTI publisher’s separate 2018 U.S. samples. The hair-color reference uses UK Biobank’s initial assessment, keeping nonanswers in the denominator and avoiding repeat visits. Neither is a worldwide census.
The hair-and-eye combination chart uses nine directly observed counts in Lin et al. (2016), Table 2(a). Its 3,619 unrelated, genotyped Dutch-ancestry participants answered surveys in 2004–2006. Full-sample shares divide by 3,619; within-hair and within-eye shares use the corresponding column or row total. The original color groups remain intact, and none of these calculations multiplies independent trait percentages or estimates worldwide prevalence.
The dog-breed and cat-breed pages count annual registrations with named UK registries. Coat and size varieties remain separate. Zero, a missing count and a category excluded from ranks are different states; none establishes extinction or a living population. Source total discrepancies and undefined percentage changes from zero are explained on the relevant page.
The fingerprint reference counts impressions, ten per participant. The dimple comparison counts people and explicitly changes the denominator when restricting to people with cheek dimples. Neither permits multiplying trait percentages into personal odds.
The perfect-pitch comparison retains approximate readings from the study’s figure, each training-age subgroup’s size and both scoring rules; exact case counts are not inferred. The synesthesia comparison distinguishes all tested forms from letter-and-number colors and keeps the university and museum samples separate. Each page links its primary source and offers every reference in a CSV with population, period, unit and uncertainty.
Keep the chart. Check the numbers.
A printable view of all 366 birthdays, plus the full table for your own spreadsheet. Both use the same 2000–2014 U.S. birth records as this calculator.
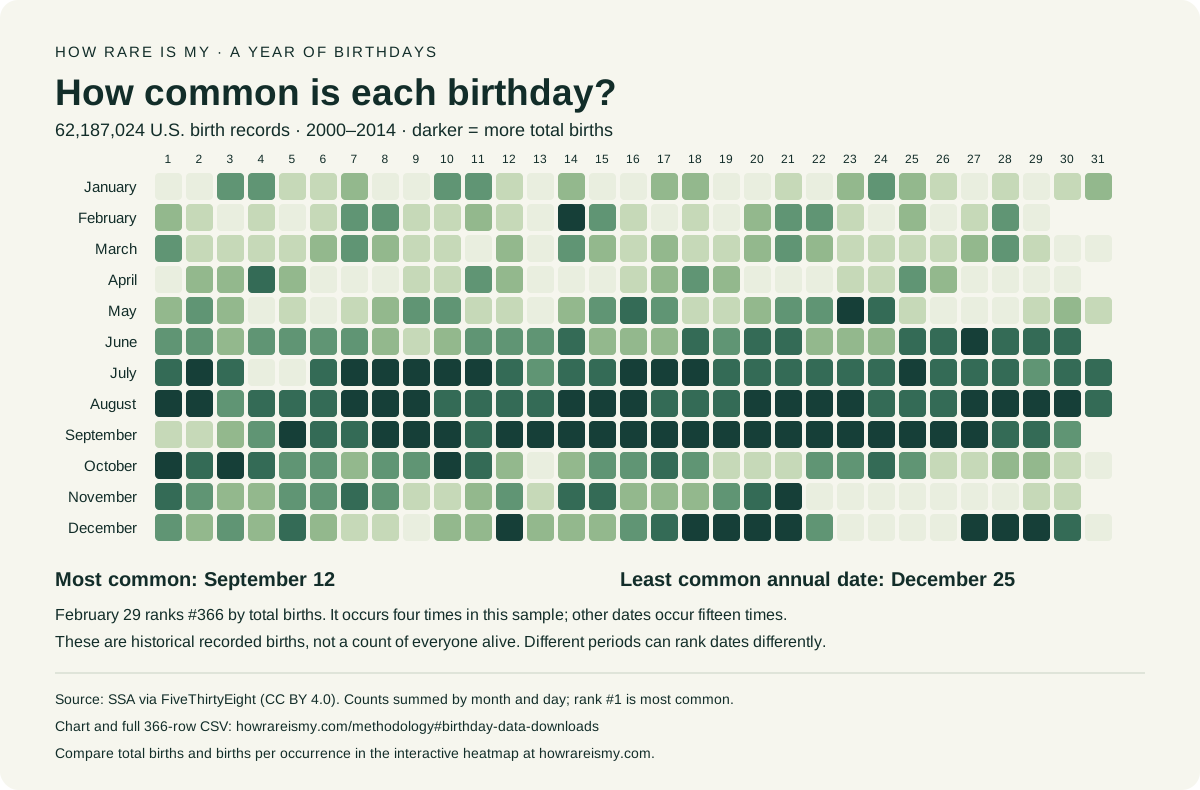
Download printable SVG Download all 366 dates (CSV)
Data: SSA via FiveThirtyEight, CC BY 4.0. We aggregate daily records by month and day. The CSV keeps counts, occurrences, ranks and the denominator so the result can be checked. Cite our sources and calculation when referring to these rankings.